Qwen3-TTS
Generate realistic speech, clone voices instantly, and design unique audio personas with Qwen3-TTS, the advanced open-source TTS model.
AI AudioFree tierWebPublic0 Views
About this product
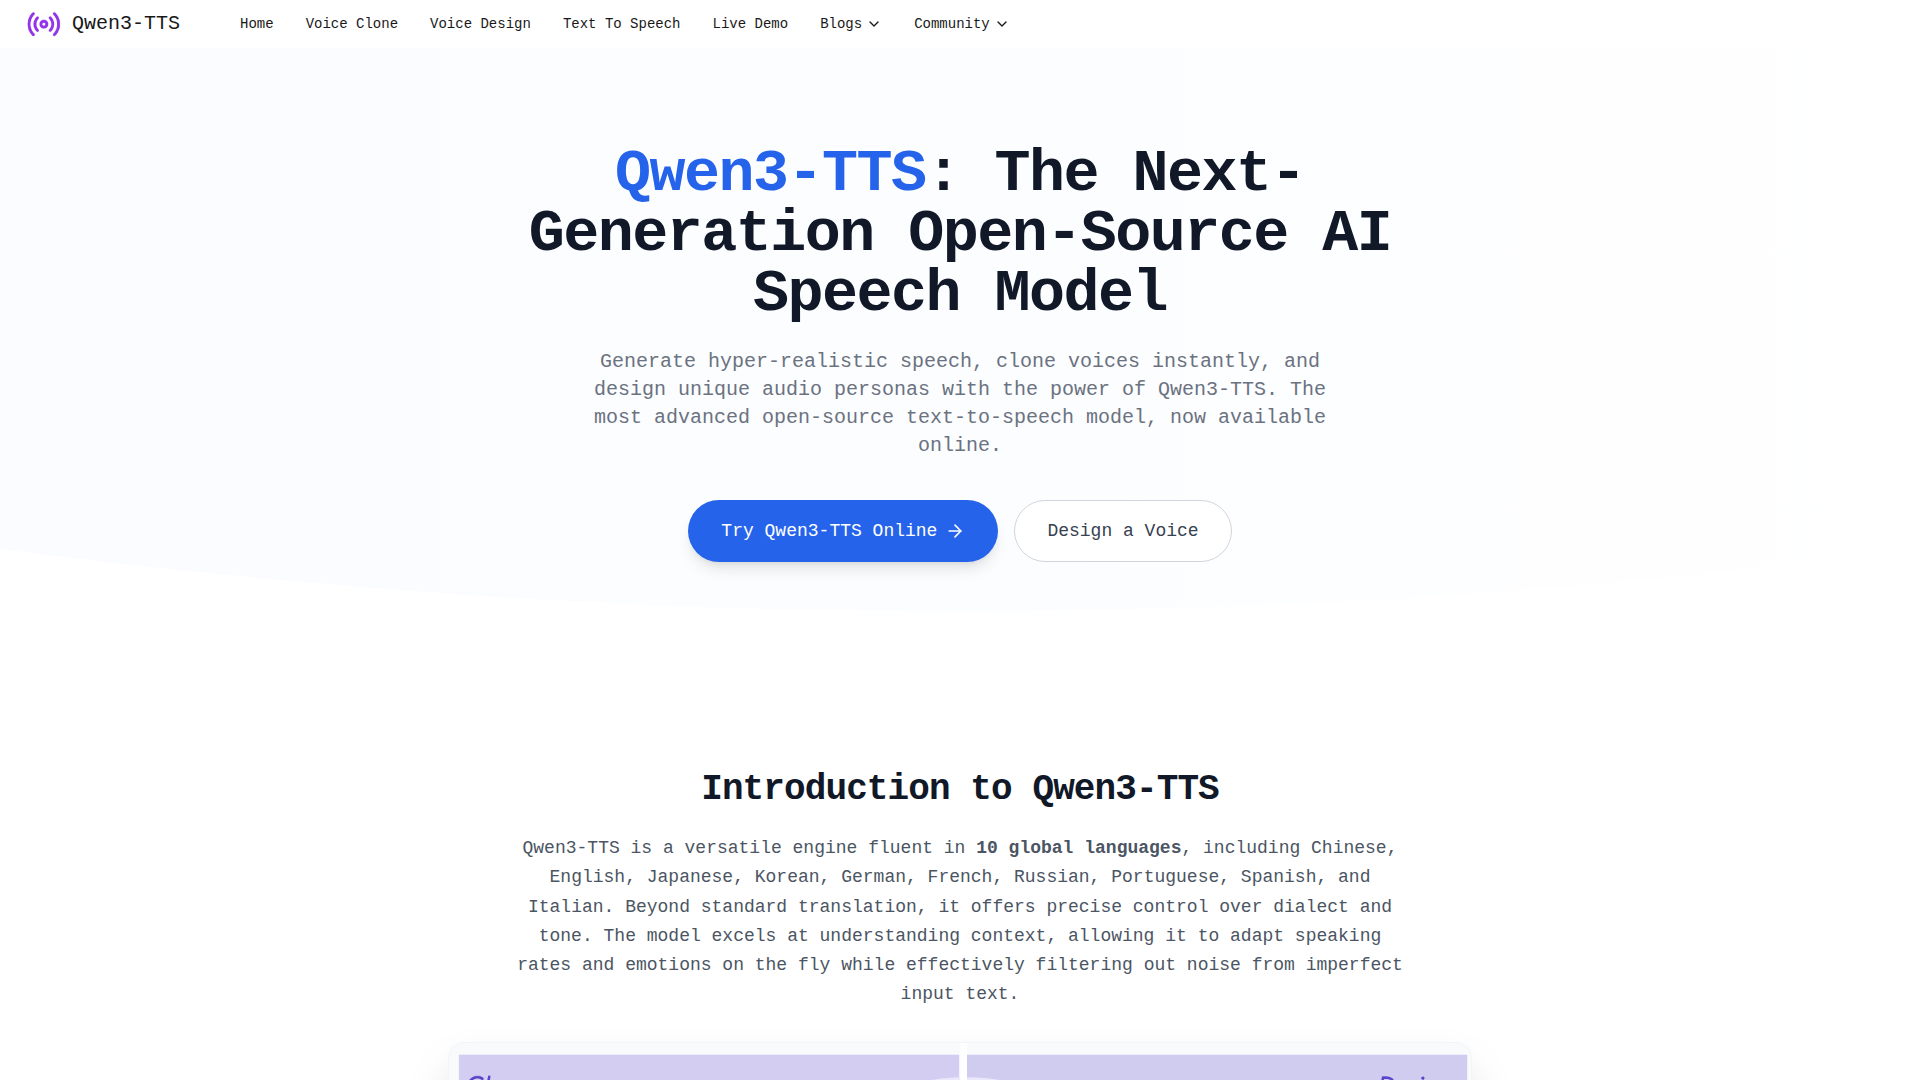
Qwen3-TTS is a next-generation, open-source AI speech model designed to generate hyper-realistic speech, clone voices instantly, and design unique audio personas. It supports 10 global languages, including Chinese, English, Japanese, and more, offering precise control over dialect and tone. Built on the Qwen3-TTS-Tokenizer-12Hz, it delivers superior acoustic compression while preserving subtle details, efficiently understanding text semantics to dynamically adapt rhythm, timbre, and emotion. With its Dual-Track architecture, Qwen3-TTS achieves ultra-low latency, making it perfect for real-time interactions and diverse applications. Whether for personal or commercial use, experience the power of advanced AI audio generation with Qwen3-TTS.
Similar products
NotebookAI PodcastGenerate professional-quality podcasts from text using AI voices and flexibility. AI STUDIOExperience AI STUDIO, the ultimate AI video generator that revolutionizes content creation with realistic avatars and advanced editing features.
 DescriptTransform your videos and podcasts with Descript's innovative text-based editing tools and AI capabilities, streamlining your creative process.
AI STUDIOExperience AI STUDIO, the ultimate AI video generator that revolutionizes content creation with realistic avatars and advanced editing features.DescriptTransform your videos and podcasts with Descript's innovative text-based editing tools and AI capabilities, streamlining your creative process.